
From Seeing to Understanding: Ziquan Liu's Research on Visual Reasoning in AI
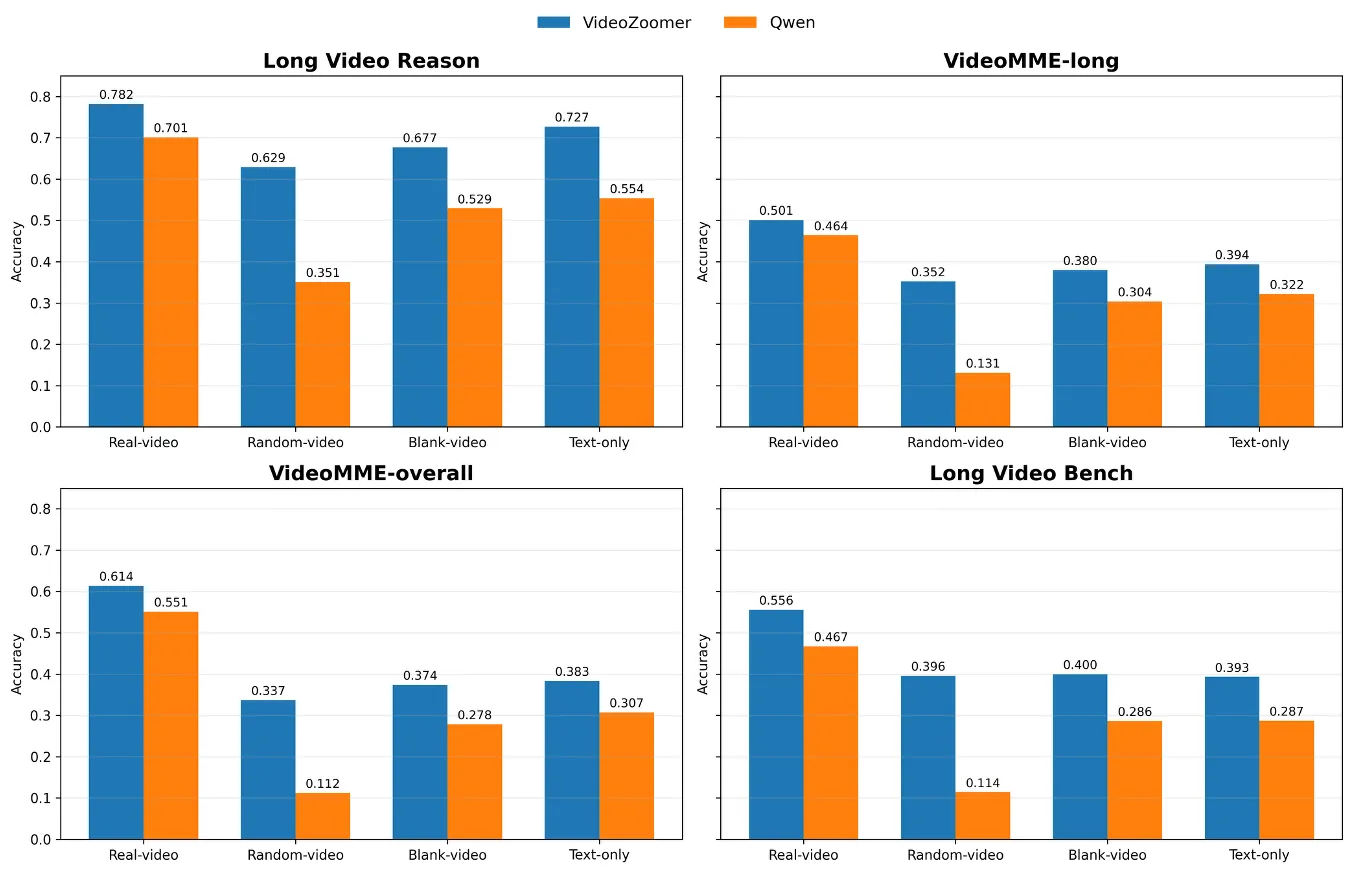
Multimodal large language models are designed to “see” as well as read. Give them a video and a question, and they can often produce an impressively fluent answer. But are they actually looking?
Our research challenges a basic assumption behind today’s multimodal AI: that when a model is given visual information, it actually uses that information to reason. We uncover a striking form of visual blindness. In many cases, models continue to answer correctly even when relevant video frames are shifted, replaced with unrelated footage, removed, or even made completely blank. Worse, they can confidently describe visual events that were never shown at all, effectively fabricating a visual reasoning process.
Why? The model may be exploiting shortcuts: patterns in the question, the answer choices, common sense, and knowledge learned from text. Indeed, a surprisingly large fraction of its performance remains even when no video is provided.
This matters because a convincing answer is not the same as a grounded answer. In healthcare, robotics, autonomous systems and other high-stakes applications, we need AI that knows when seeing is necessary, checks the evidence, and changes its mind when the evidence changes.
We therefore move beyond simply measuring accuracy. We investigate signals that reveal when a model is relying on language rather than vision, and explore ways to redirect its reasoning towards visual evidence. Simply suppressing language shortcuts is not enough: what is missing is a mechanism that makes the model actively seek visual evidence when uncertainty demands it.
Our ambition is simple but fundamental: not AI that merely has eyes, but AI that knows when and how to use them.